BioBasicsBench shows AI can assist lab work, but should not own the workflow
GPT-6 Astra earned 66.7% of available credit across 100 tasks built from raw laboratory evidence. What it still gets wrong matters more for production.
What changed
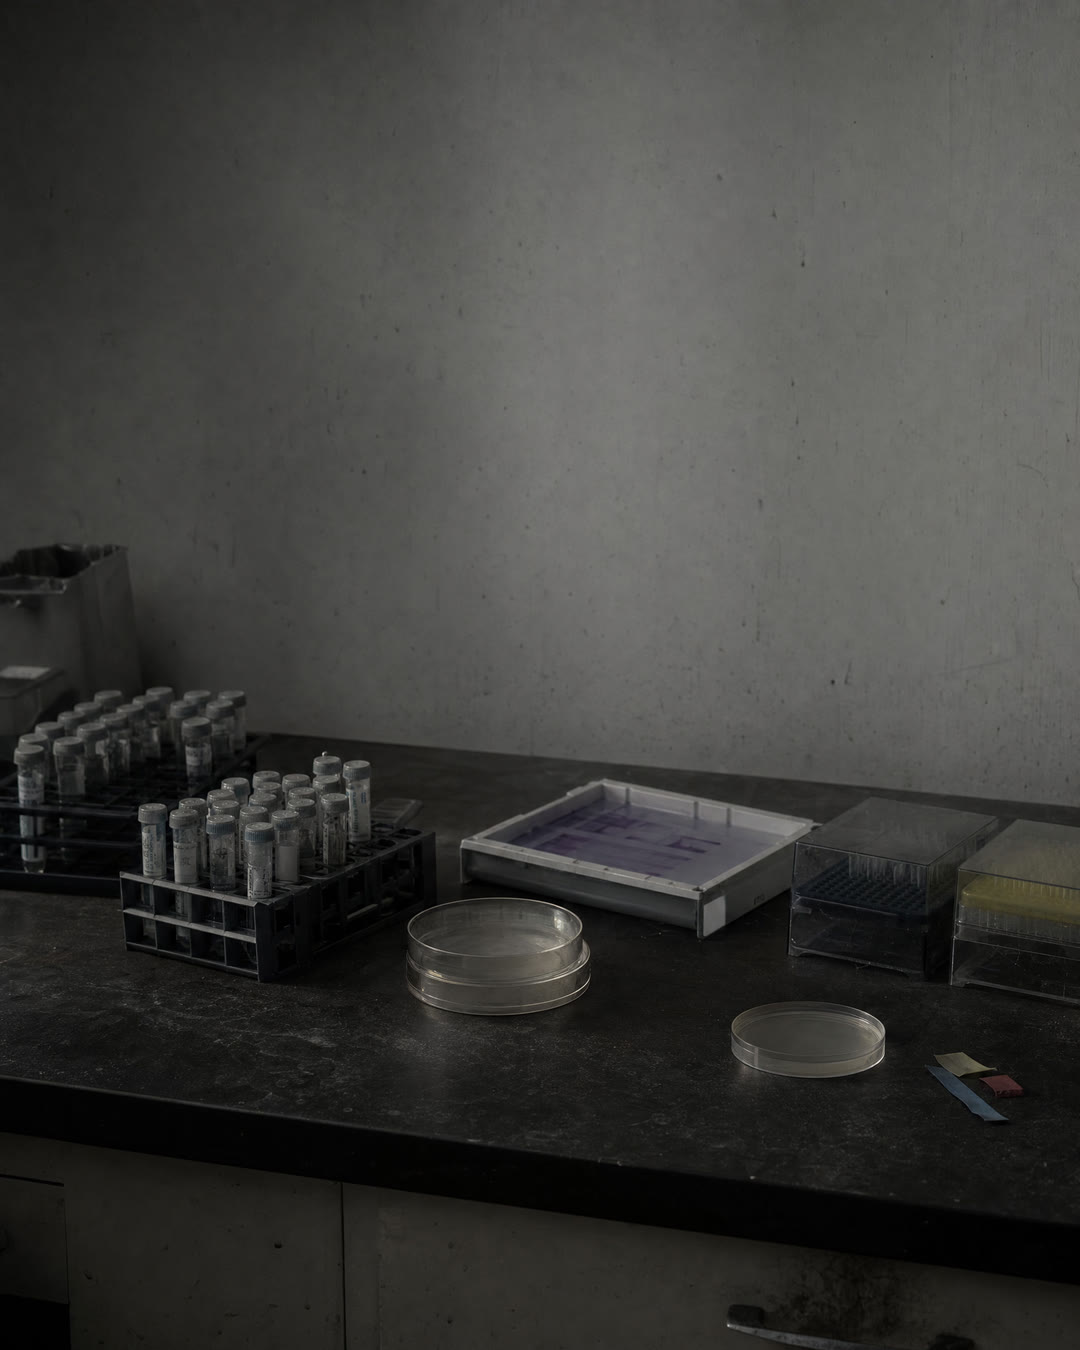
On November 6, OpenAI and Ligo introduced BioBasicsBench, a set of 100 tasks built from raw laboratory evidence including gels, microscopy, colony plates and instrument outputs. At the highest shared reasoning setting, GPT-6 Astra earned 66.7% of available rubric credit, versus 43.8% for GPT-5.6 Sol.
The score misleads
The 66.7% figure is average rubric credit, not the share of tasks completed correctly. Published failures show Astra selecting the wrong controls, discounting contradictory observations and miscounting colonies even after making useful intermediate observations.
The production boundary
That is good enough for triage, a second reading and preparation for expert review. It is not good enough for irreversible autonomous decisions, so a production system should preserve evidence, expose uncertainty, require approval and measure performance on its own cases.
Virtual Arc’s view is that BioBasicsBench is a green light for assisted analysis and a red light for autonomous scientific judgment. GPT-6 Astra’s jump to 66.7% of available rubric credit, from 43.8% for GPT-5.6 Sol, is meaningful, but it is not a task-completion rate and it still leaves too much room for wrong controls, discounted evidence and bad counts. We would not wire this model directly into a workflow that orders experiments, releases batches or updates a system of record. We would deploy it as a second reader: force structured evidence citations, make uncertainty explicit, route contradictions to a human and shadow-test it against the team’s own historical cases. Because the published comparison covers only OpenAI models and the task set is not available for independent runs, choosing Astra from this result alone would also create unnecessary vendor lock-in. The unit that matters is not price per token; it is cost per correct, reviewed decision, including rework when the model is confidently wrong.
Turn insight into a working system.
We would build a shadow-tested analysis pipeline that extracts evidence, checks controls, records provenance and routes uncertain conclusions to a human before any downstream action. Virtual Arc would compare providers on your own cases and add permissions and audit trails. Talk to us if your team turns messy scientific or inspection data into operational decisions.